Architecting Cost-Conscious AI Workflows
Cost-conscious AI workflows are designed, not tuned after the fact. Discover six architecture decisions that cut wasted tokens and help control spending.
- AI Workflows
- AI Cost Management
- AI Agent Budgets
- Agent Operations
We tend to describe AI in deeply human terms. It thinks and reasons. It plans ahead.
But AI lacks common sense. Left unconstrained, an autonomous agent will pursue a given goal with no sense of efficiency or fiscal responsibility. It'll make repeated tool calls and accumulate bloated context. It'll retry the same failed approach again and again, running up token costs.
Restraint isn't something that just magically happens. It has to be built in. But how do you architect a cost-conscious AI workflow?
The key is to design for efficiency from the start. Let's explore how.
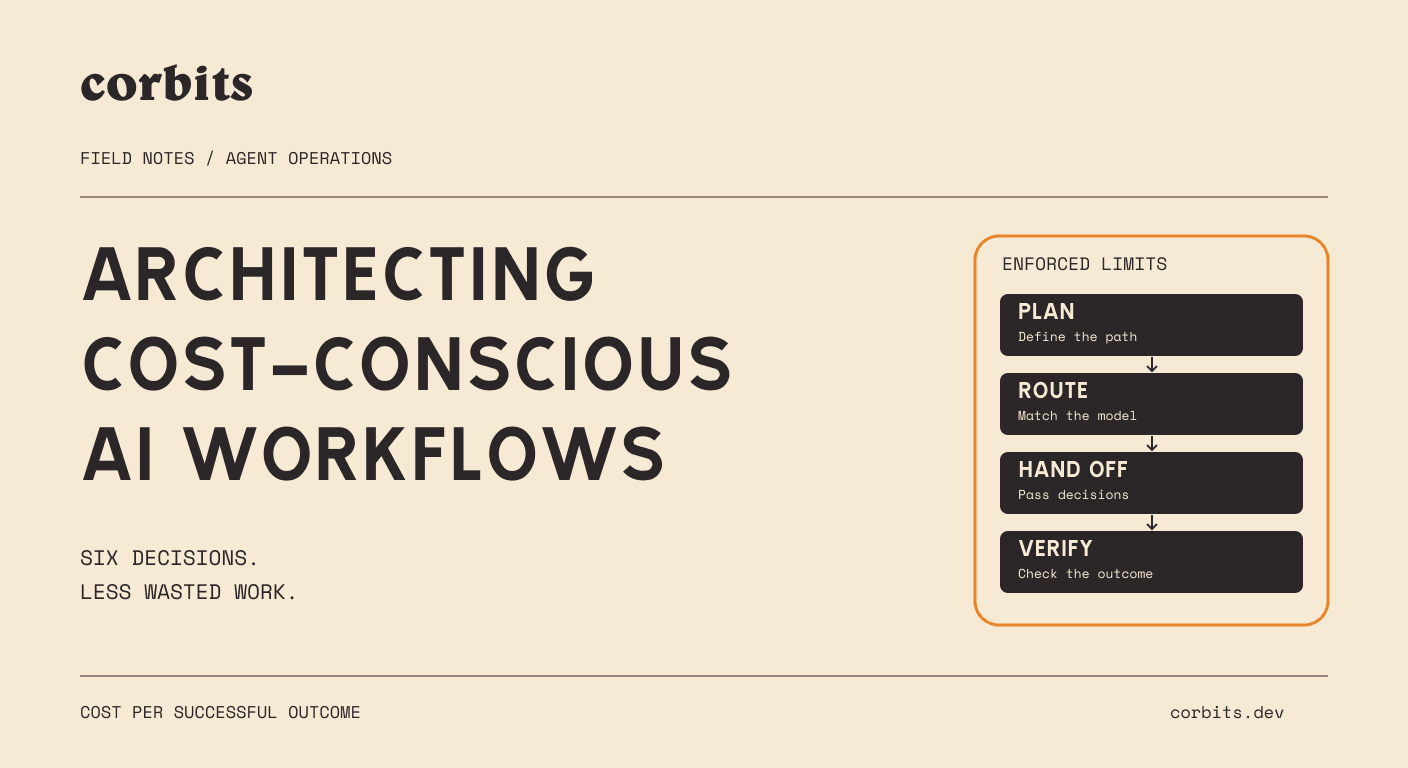
1. Start With the Right Unit of Measure
If we're talking about cost efficiency in an AI workflow, we need to look at how we define cost.
Cost per run can be helpful, but it doesn't convey the full picture. For instance, a $0.40 run that fails and has to be redone ends up costing more than a $0.70 run that gets it right on the first attempt.
A better measure is cost per successful outcome. It's how much you spend on average to complete a task successfully. You divide the total cost of all runs – including failed attempts and retries – by the number of verified, successful outcomes.
This measure changes how you judge each step. For instance, an extra verification step admittedly raises the cost of a run. But if it catches errors that would otherwise force a redo, and saves more than it costs, then overall it lowers the cost per successful outcome.
2. Decide the Path Before Spending Anything
Let's look at an example run. A team of AI agents is asked to research a competitor and write a two-page report. That means the path forward involves searching for information, retrieving facts, synthesizing data, drafting the report, and reviewing it.
Before the first model call even happens, the workflow should already know the steps it'll follow.
This involves declaring the graph upfront. A declared graph of steps, as opposed to an open-ended agent loop, gives the workflow a defined structure and clear conditions for moving between steps.
We cover the difference in more detail in AI Agent Orchestration vs. Workflows, but the cost benefit is that declared graphs make it easier to anticipate resource requirements and limit unnecessary work while keeping everything within predictable boundaries.
So, in our competitor research example, the workflow might filter through twenty search results with a quick relevance check, and then only do a closer reading of the best five results. If nothing worthwhile turns up, the deeper analysis (which costs more) doesn't happen.
3. Route Each Step by Difficulty
Something simple like extracting dates and numbers from a source document doesn't require the use of an advanced AI model. But synthesizing and reconciling information from ten different sources might.
To optimize spending, each step in the workflow should be handled by the least expensive option that can get the job done well. This can include:
- Deterministic code for tasks with predictable rules.
- A smaller model for straightforward data extraction and classification.
- A more capable model for synthesis and judgment calls.
The trick is to avoid paying for more intelligence than a task actually needs.
But once each step has the right tool for the job, the next challenge is making sure it gets the right information.
4. Hand Off Decisions Instead of Transcripts
Our example workflow is now at the report-drafting step, and the agents have accumulated a lot of context: search results, facts and figures, tool outputs, and conversation history.
Sending all of this information to the next agent is overkill. It wastes tokens and results in prompt bloat. The question is, what does the next step need in order to execute correctly?
The answer is structured state, rather than a full transcript. Agents should pass along only whatever information is needed to process the next link in the chain. Namely, things like the original goal, findings, supporting evidence, any remaining uncertainty or open questions, and any constraints that are still in effect.
We discuss the reliability angle in Context Loss in Multi-Agent Systems, but clean handoffs are also good for cost savings. A concise, structured handoff is less costly to process and harder to misread. This in turn reduces retries and delays.
There is a limit, though. If you cut out too much, the next agent ends up with blind spots – and that can be a more expensive problem than using up a few extra tokens.
5. Cap the Loops and Checkpoint the Work
Let's say the next agent in our example drafts the report... but it fails the review. So the agent rewrites it, submits it again, and fails a second time. This loops several times. Every retry burns through more tokens and compute, and drives up the cost per successful outcome.
To save money, runaway loops and repeated or wasted work should be stopped. Here are some general rules to follow:
- Cap retries. Set a maximum iteration count; each retry represents additional spend.
- Change strategy upon repeated failure. If the same error keeps coming up, don't keep using the same approach.
- Define stopping conditions. Decide beforehand what counts as success or failure, and when a human needs to be pulled in.
- Checkpoint completed steps. Runs should resume from where a failure occurred, to minimize duplicated work.
The right limits depend on the task. For instance, a research workflow might actually benefit from a few extra searches, since each one may turn up something new. Meanwhile, a code-generation workflow might need stricter caps on code testing and repair loops that end up going nowhere.
6. Set Enforcement Outside the Agent
Agents can and should make money-related decisions, including optimizing costs on their own. But for safety's sake, decision-making must stay separate from enforcement.
You can't plan for everything. A task might end up being unexpectedly costly or much more difficult than you thought. A service can fail repeatedly. Optimization means doing your best with the information you have at the time.
But agents can be poor judges of their own spend. In one study of coding agents, token use on the same task varied by up to 30x between runs, and models failed to accurately predict their own token consumption.
That's why, as we explain in Can AI Agents Manage Their Own Budgets?, hard limits belong in the infrastructure around the agent, where it can't override them. These include things like maximum spend per run, usage quotas, per-agent spending caps, and tool permissions.
If you haven't defined those limits yet, start with our guide on how to set an AI agent budget.
Make Cost Efficiency an Architectural Decision
Cheaper AI models help. But the biggest cost savings come from your workflow's architecture: how it plans, what it runs, what it remembers, and when it stops.
Build cost efficiency in from the start. We can help.
See your agents, govern what they do, and prove it to anyone who asks.